What Should a QA Leader Actually Own in 2026?
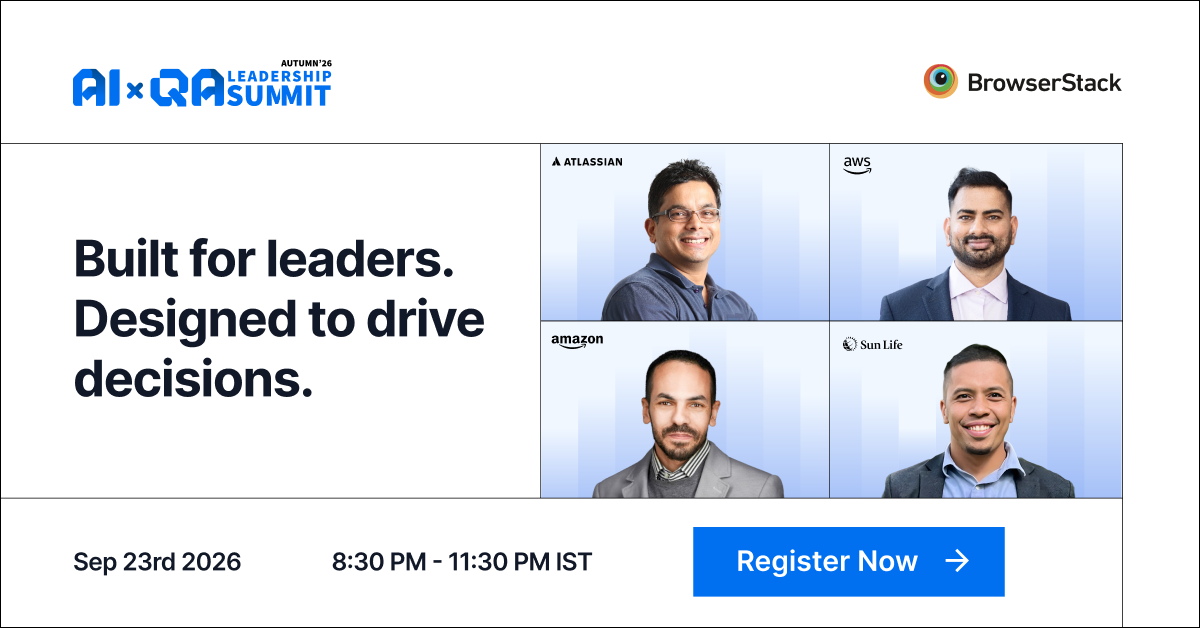
A few years ago, the challenge was getting more testing done. Today, QA leaders are asking a different question: where does QA create the most value when software can be built and tested in entirely new ways?
Join BrowserStack’s QA Leadership Summit 2026 on September 23rd to hear leaders from Atlassian, Amazon, AWS and more share how they are rethinking QA strategy, governance, metrics and everyday testing.
Butch's Take
As you work with skills with your AI coding agents, it's always good to preform regular maintenance on your skill files and skill usage. Over time your skills may grow with technical debt or there may be information in the skills that is no longer necessary due to new model updates. Here are a few commands within claude code that can help manage/maintain your skills and CLAUDE.md files.
/skill-doctor — which skills you actually use
/skills, then t — what each one costs
/doctor — fixes setup and CLAUDE.md debt
/context — what's in the window right now
/usage — what's burning your limits
The two I'd start with: /skill-doctor and /doctor. Most people have dead skills loaded they haven't invoked in weeks, and every one of them eats window space before your prompt even fires. The doctor command specifically targets reviewing your CLAUDE.md file which also gets loaded every single time into context. Doing this every so often (once a month) can help ensure you are keeping your context window clean and aren't needlessly burning tokens. Five minutes of cleanup before your next session. That's all that is needed.
Headlines & Launches
Dario Calls Testing and Evaluation One of Software's Most Serious Problems
Rahul Parwal (LinkedIn)
Parwal highlights Anthropic's CEO Dario Amodei calling testing and evaluation one of the most valuable, difficult, and serious areas in software today, and marks the shift from 'testing is dead' talk to 'we need better testing.' The comment thread is where it gets good: independent evaluators as second opinions, and whether orgs will fund skilled testers rather than only more automated evals.
Angie Jones' Agent Skills Course Adopted by Four Universities
Angie Jones (LinkedIn)
Angie Jones' course on Agent Skills is now being distributed through Johns Hopkins, Merrimack, Kean, and Calvin University. University programs adopting practitioner-built AI-agent training signals that agentic skills are entering formal engineering curricula, with industry instructors moving faster than traditional courseware.
AI Verification Debt: When Generation Volume Outpaces Review
Ruslan Desyatnikov (LinkedIn)
Ruslan Desyatnikov, names the hidden cost of AI-generated testing artifacts: AI verification debt. AI produces 5,000 test cases where a tester wrote 25, but duplicates, low-value cases, and review hours move the work rather than remove it, while management sees impressive numbers. He calls for measuring acceptance rates, duplication, correction effort, and risk coverage instead of celebrating generation counts. An AI-generated test case is a suggestion, not proof of quality.
Will We Stop Reading Code and Focus Solely on Behavior and Tests?
Cory House (X)
Cory House asks the question sitting underneath this debate: as AI writes more of the code, will developers stop reading it entirely and judge software solely by behavior and tests? Posted the day this issue was assembled, it drew rapid discussion. The obvious companion to Doronins' planted-bug experiment: what happens when the tests you trust instead of the code were themselves AI-written and wrong?
Tools & Frameworks
vibe.check() Lands in Vibium
Jason Huggins (LinkedIn)
Selenium creator Jason Huggins shipped vibe.check() to vibium main: an agent-first CLI where 'vibium check
Agentic Playwright: A Scaffold Built for Claude, Cursor, and Copilot
alexusadays (YouTube)
A video review of Agentic Playwright, an open-source Playwright and TypeScript scaffold built specifically for agentic testing. The repo pairs a working structure (page objects, dependency-injected fixtures, API tests with Zod validation, data factories, auth, CI, multi-browser) with a Constitution and 17 AI skills that steer Claude Code, Cursor, and Copilot away from hard waits and XPath selectors. Reviewer's honest framing: it is a scaffold and rule system, not a finished framework. Repo: Agentic-Playwright by Ivan Davidov.
Microsoft's AI Engineer Coach Scores Your AI Coding Habits
Deepak Kamboj (GitHub)
Microsoft open-sourced a VS Code extension that reads your local AI coding session logs (Claude Code, Copilot, Cursor, Codex, Cline) and scores how well you actually drive the tools: practice trends, AI-code volume by language and model, 45 anti-pattern rules across prompt quality, session hygiene, and context management, plus readiness checks on your instruction files. Everything stays local. Useful for QA teams that want evidence their AI usage is improving, not just increasing.
Google's ARTEMIS Drives Real Android Devices
Google (GitHub)
Google open-sourced ARTEMIS, which turns natural-language instructions into Android automation on real devices: cross-app workflows, Logcat capture, screenshots, and an MCP server so agents like Claude Code, Codex, or Antigravity can drive phones. It claims 99%+ task completion on the AndroidWorld benchmark (100+ multi-step tasks). Ships with a testing-mindset rules file that installs into your AI IDE.
Mosaik: Agentic Browser Automation Built From Small, Reusable Pieces
luantak (GitHub)
An open-source framework where an agent explores a site once, saves what it learns as TypeScript actions, then composes them into automations that run through Playwright deterministically, with no model call per step. Aimed at consistent execution at scale: same extraction rules across thousands of records, same journey check after every release. A separate model pass reviews each run's evidence, and marked side-effect steps (payments, sends) are never auto-retried. Currently in alpha, expect breaking changes.
Techniques & Tutorials
Every Time You Correct Your Agent, Eliminate the Intervention
@poteto (X)
Lauren (React compiler core team, ex-Cursor/Meta/Netflix) ranks responses to manually correcting an AI agent, best to worst: 1) eliminate the problem categorically through architecture or data structure choice, 2) turn it into a lint rule or test CI catches, 3) encode it as a skill or rule, 4) humans reviewing code to catch it.
AI Is Making Test Automation Faster. What About Maintainability?
Vaibhav Singhal (LinkedIn Pulse)
Singhal opens with an SDET who could extend the automation suite only by asking AI, and could not read it alone. That gap is his subject: generation is faster (30-40 green tests a day), but validation, review, and ownership remain human, and valid code can still shift semantics (a Promise.all 'cleanup' turns sequential setup concurrent). Eight practices follow: team coding standards as AI context, review the test not the code, small PRs, separate review bars for framework vs test code, regular pruning, keep human owners.
Corrective vs Prescriptive Agent Skills: Are You Explaining What a Model Already Knows?
Antony Marcano (LinkedIn Pulse)
Marcano splits agent skills into prescriptive (carry the whole workflow, for things the model can't know) and corrective (undo misconceptions the model absorbed from training data, for well-documented practices like TDD). His corrective TDD skill shrank to two clauses after batch-testing agent runs until failures dropped below 1 in 100, his TDAB pattern (test-driven agentic behaviours). The gap he flags in Anthropic's guidance: what to do when the model knows something wrong.
Computer Use Agents are Excellent QA Engineers
Tristan Rhodes (tristanrhodes.com)
A founding engineer's working setup for a computer-use agent as autonomous QA: give it its own email with user-impersonation rights, repo read access, and issue-tracker write access, so it straddles the user's black-box view with the developer's transparent one. Nightly, it parses commits into atomic features, plans happy paths and creative edge cases, then files richly documented bugs to Linear and Slack. His morning Slack: overnight catches of his own bugs, with repro steps.
Hot Take 🔥
Agentic or Not, Here It Comes
Chris Zeuch (X)
A QA lead's three-year retrospective: a 2023 Cursor license turned into Python tooling for his QA team, personal projects, then building in public. Today he catalogs what's changed (Skills, context management, token budgets, MCPs, Computer Use) and names the elephant: tools that could make entire QA automation teams redundant. His stance is excitement, not doom, with more thoughts promised.
Quick Links
AI Noticed the Contradiction and Automated It Anyway
Andrejs Doronins (LinkedIn)
Andrejs Doronins ran a small experiment against the 'I don't read my AI-written tests anymore' mindset. He planted a basic contradiction in a dummy trading app: a 'Your portfolio is full' message shown when the portfolio table is empty. Copilot on Sonnet 4.6 reasoned mid-task that the message made no sense, then automated a passing assertion for the wrong text anyway. His takeaway: batch-generated, unreviewed AI tests mean more useless-but-green suites.
Throw-AI-Code-Over-the-Wall vs. Quick-Check-Before-QA
Steven Boutcher (LinkedIn)
Some wise words from Steven, which lines up really well with "Don't be a meat proxy"
If something in this issue made you think differently about how your team approaches AI in testing, pass it along. The best conversations about AI and QA are happening in Slack channels and stand-ups, not just newsletters.
Have something worth featuring? Reply and send it my way, I read every link.
Thanks for reading,
Butch Mayhew
